说明
数据如下,使用 MapReduce 框架,统计平均分数
数据
李雷,80
lucy,90
lili,100
韩梅梅,70
java 代码
mapper
package score;

import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Mapper;

import java.io.IOException;

public class ScoreMapper extends Mapper<LongWritable, Text,Text,LongWritable> {
    // hadoop 实现序列化好处之二:复用同一个对象
    private Text k = new Text("score");
    private LongWritable v = new LongWritable();

    @Override
    protected void map(LongWritable key, Text value, Mapper<LongWritable, Text, Text, LongWritable>.Context context) throws IOException, InterruptedException {
        String line = new String(value.toString().getBytes(), "UTF-8");
        String[] arr = line.split(",");
        Long score = Long.parseLong(arr[1]);
        v.set(score);
        context.write(k,v);
    }
}
reducer
package score;

import org.apache.hadoop.io.DoubleWritable;
import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Reducer;

import java.io.IOException;

public class ScoreReducer extends Reducer<Text, LongWritable, Text, DoubleWritable> {
    private DoubleWritable v = new DoubleWritable(0);

    /**
     *
     * @param key 是 map中keyout,如:李雷
     * @param values 如果有4个李雷,那么就是   1,1,1,1
     * @param context 收集数据
     * @throws IOException
     * @throws InterruptedException
     */
    @Override
    protected void reduce(Text key, Iterable<LongWritable> values, Reducer<Text, LongWritable, Text, DoubleWritable>.Context context) throws IOException, InterruptedException {
        Long sum = 0L;
        Long count = 0L;
        for(LongWritable item : values){
            sum = sum + item.get();
            count ++;
        }
        Double avg = ((double)sum) / count ;
        v.set(avg);
        Text k = new Text("平均分:");
        context.write(k,v);
    }
}
主启动类
package score;

import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.DoubleWritable;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Job;
import org.apache.hadoop.mapreduce.lib.input.FileInputFormat;
import org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;

import java.io.IOException;

public class Main {

    public static void main(String[] args) throws IOException, ClassNotFoundException, InterruptedException {
        //创建 config 对象
        Configuration config = new Configuration();
        //构建 Job 实例,设置job名字,在yarn 8088可看到
        Job job = Job.getInstance(config,"mywordcount");
        //设置jar加载路径,不加此代码有时可能会报错
        job.setJarByClass(Main.class);
        //设置map和reduce类
        job.setMapperClass(ScoreMapper.class);
        job.setReducerClass(ScoreReducer.class);
        //设置map输出 key/value 类型
        job.setMapOutputKeyClass(Text.class);
        job.setMapOutputValueClass(LongWritable.class);
        //设置最终输出 key/value 类型
        job.setOutputKeyClass(Text.class);
        job.setOutputValueClass(DoubleWritable.class);
        //根据输入参数 设置输入和输出路径
        FileInputFormat.setInputPaths(job, new Path(args[0]));
        FileOutputFormat.setOutputPath(job, new Path(args[1]));
        //job.submit();//这种提交较少用,原因在下面
        //一般采用这种方式提交,等待结束,客户端可实时看到进度
        boolean result = job.waitForCompletion(true);
    }
}
测试
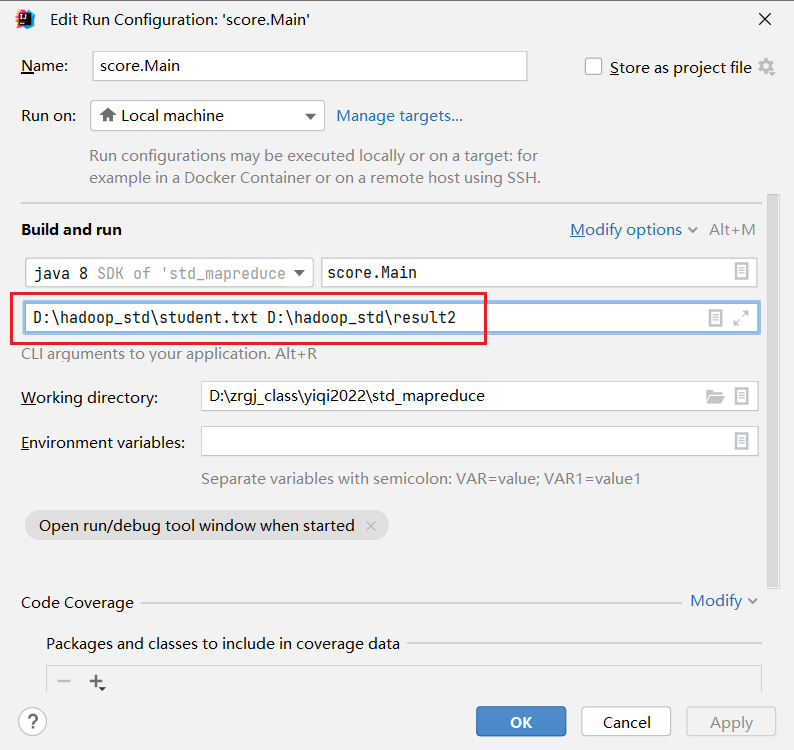
启动时设置参数:
D:\hadoop_std\student.txt D:\hadoop_std\result2
如下图红框处: